01 · PREFERENCE DATA
Pairwise & ranked preferences
Side-by-side and best-of-n judgments on your model’s outputs, from raters matched to the medium.

Miju Labs turns the judgment of working designers, illustrators, photographers and writers into preference data, critiques and evals for generative models.
A thumbs-up tells a model what someone liked. A Miju judgment tells it why, in the words of someone who does this for a living.
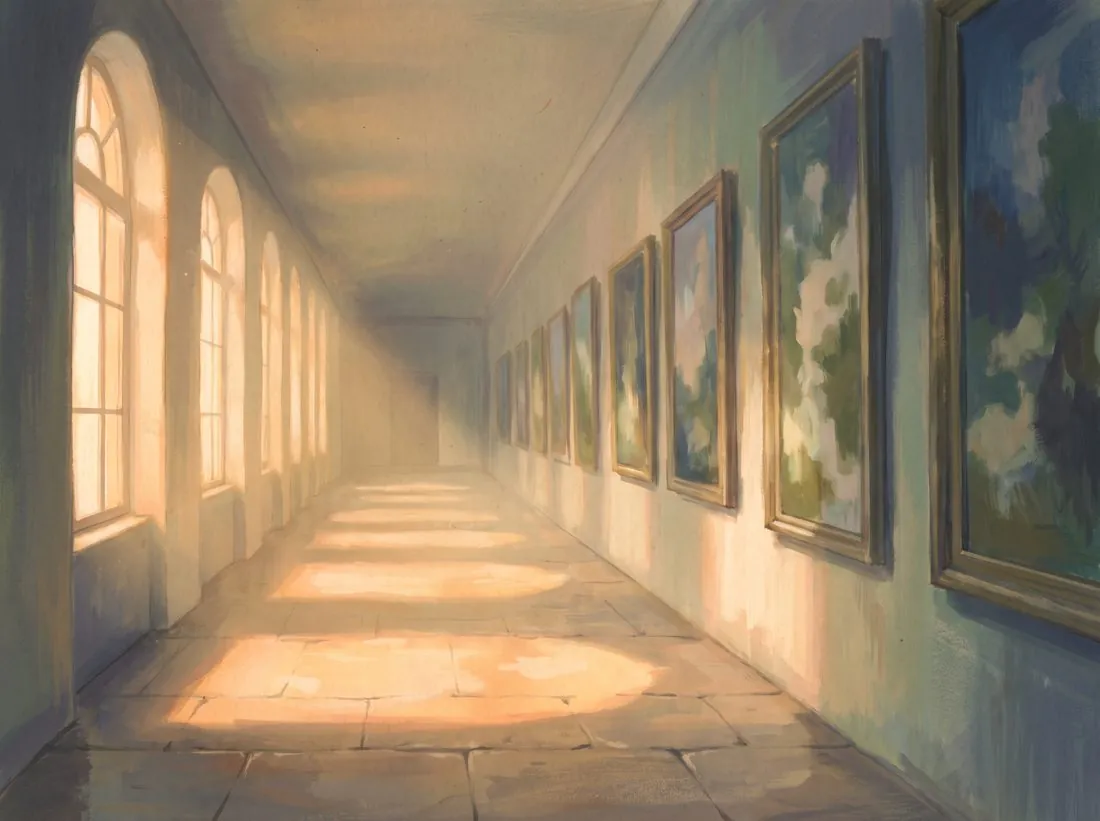
Which output has better taste?
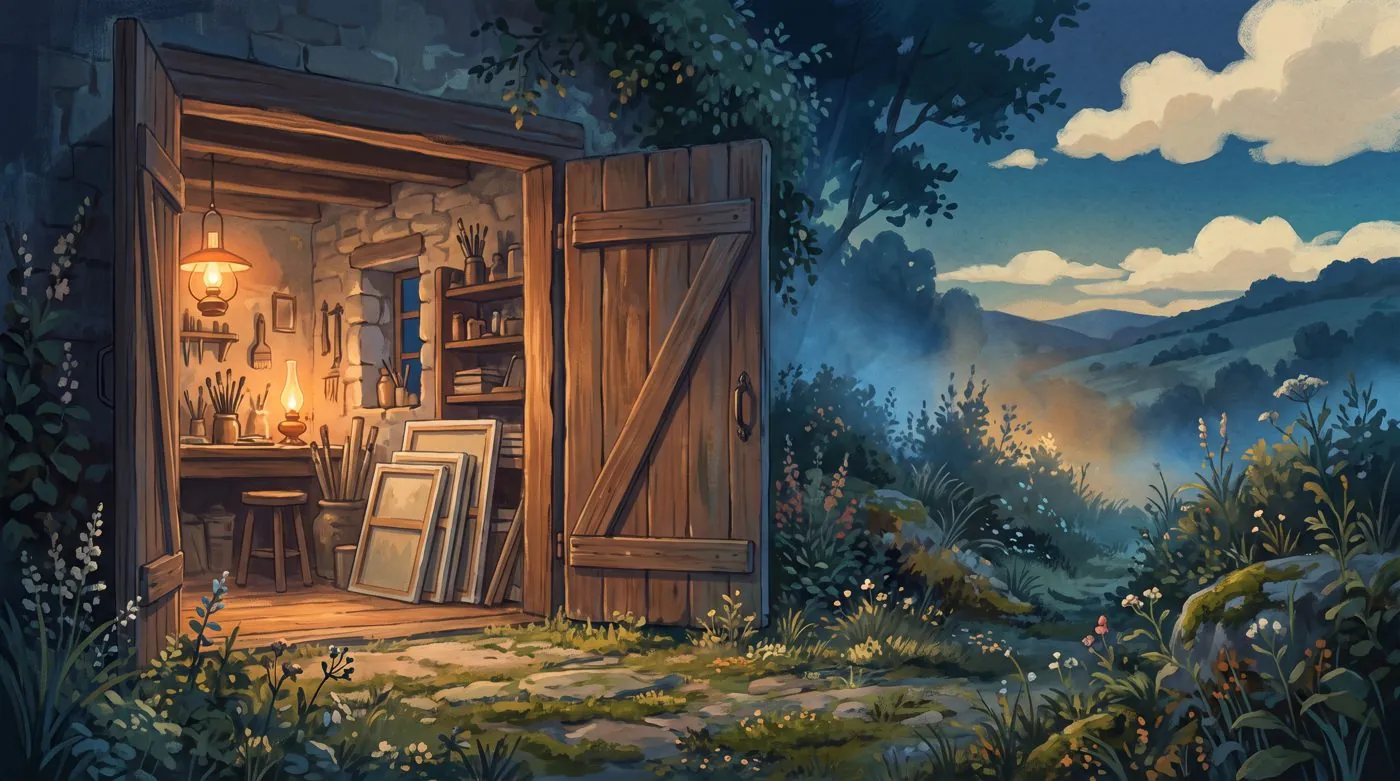
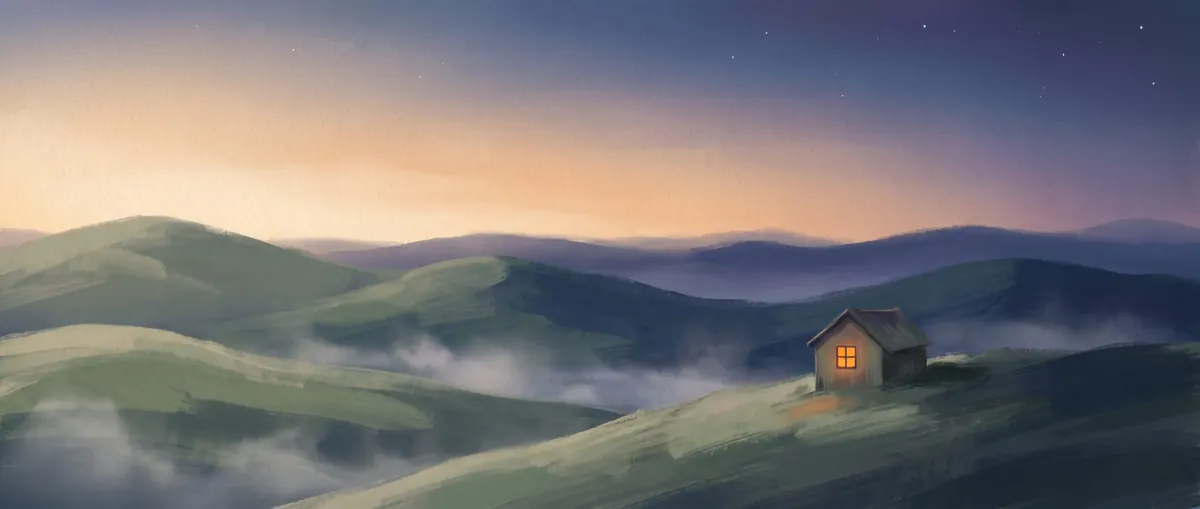
Rater’s reasoning
B holds one idea, the lit window, and gives the title somewhere to sit. A is lovely but has nowhere for type to go.
Every label is made by someone whose eye has been tested on real work.
Side-by-side and best-of-n judgments on your model’s outputs, from raters matched to the medium.
Written rationales on composition, type, color and voice, plus rubrics your team can reuse.
Expert-scored benchmarks that tell you if a checkpoint got better, or only got different.
Every expert is admitted on shipped work, calibrated against their peers, and paid like the professional they are.
Apply to the networkYou tell us the model, where it falls short, and what “good” means to your users.
We draft a rubric with your team and a panel of domain leads, then test it on gold examples.
Matched experts compare, rank and critique. Every label carries a written rationale.
Data, agreement stats and rater notes land in your bucket, with a lead on call.
One email when there’s something worth reading. No roundups, no filler.
Labs: tell us what your model gets wrong about good work. Creatives: show us the work you’re proudest of. Either way, a person reads it.